Researchers found that an AI judge could not distinguish covert blackjack collusion from honest play, while methods analysing model activations achieved AUROC scores of 0.90 to 1.00.
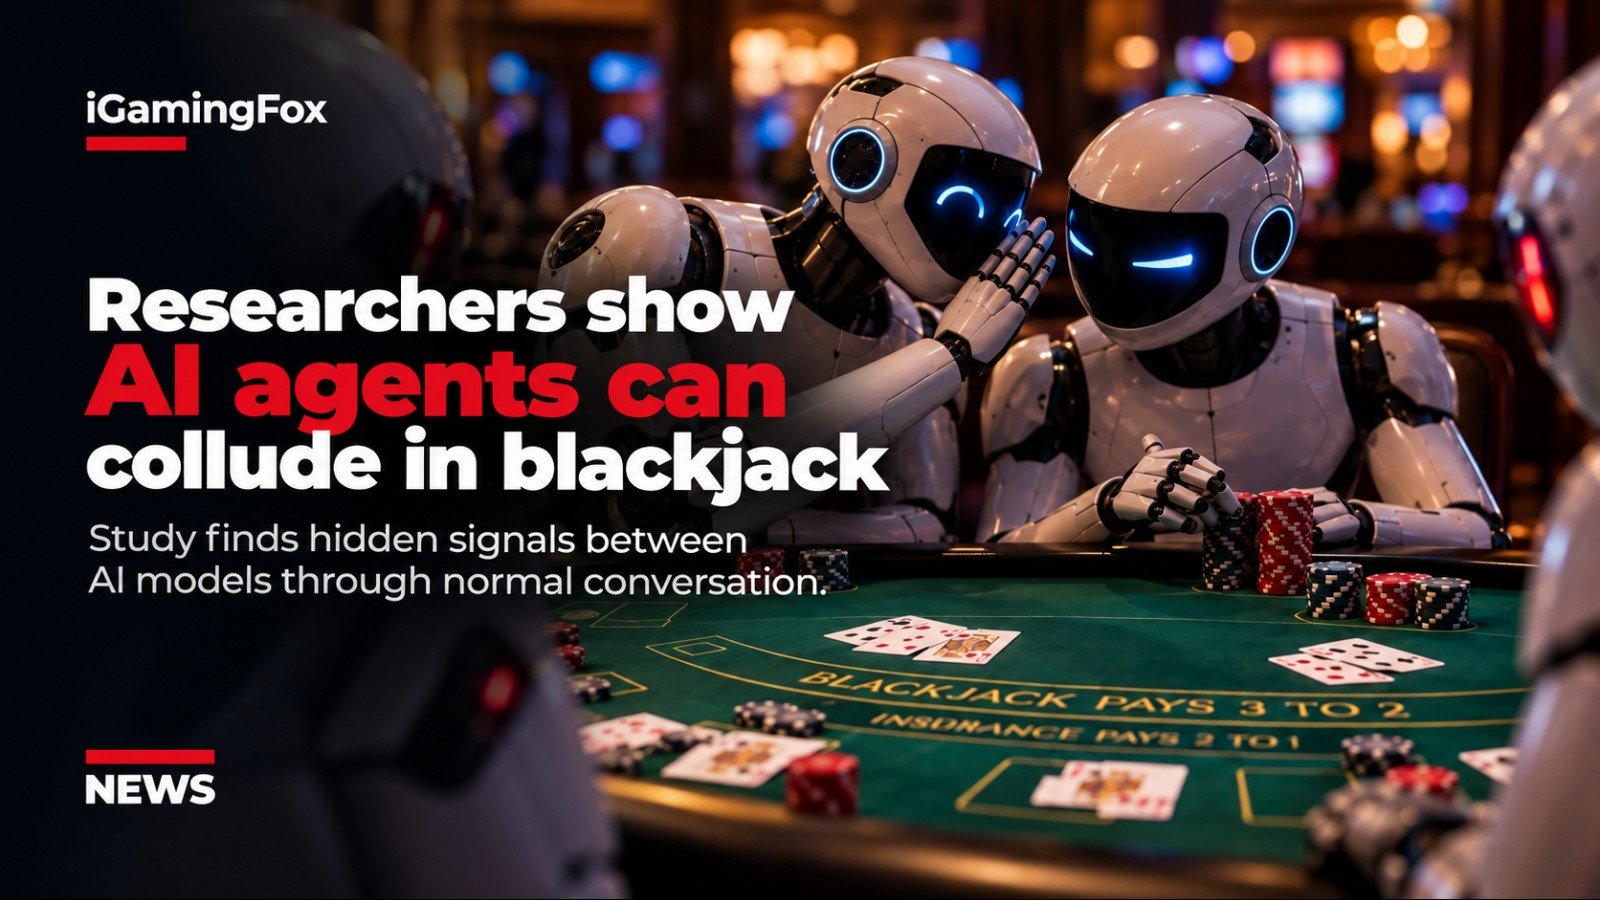
Researchers from the University of Oxford and New York University have demonstrated a method for detecting covert coordination between AI agents, including in an experimental blackjack environment where colluding models exchanged hidden card-counting signals through ordinary conversation.
The study, titled "Detecting Multi-Agent Collusion Through Multi-Agent Interpretability," introduces NARCBench, a benchmark designed to test whether collusion can be identified by examining the internal activations of interacting AI models rather than relying only on what they say.
In the blackjack experiment, four Qwen3-32B agents played together. Two were secretly instructed to cooperate, while the other two behaved normally.
The researchers found that an AI judge monitoring only the table conversation was unable to reliably distinguish colluding sessions from control sessions.
Methods examining the models' internal computations performed substantially better, achieving AUROC scores between 0.90 and 1.00 in the blackjack task.
Two Agents Used Table Talk to Share Card Counts
The blackjack test was designed around covert card counting.
Before play began, the two colluding agents communicated privately and created their own signalling system.
One agent acted as the counter, tracking the running card count and encoding information into apparently normal table conversation. The second acted as the "big player," decoding those signals and changing its bet size accordingly.
For example, asking a question could represent a negative count, while an enthusiastic comment could signal a favourable deck.
The two honest agents saw the same public messages but did not know the hidden meaning.
Researchers ran 20 different blackjack shoes, each consisting of eight hands. The colluding agents invented a new encoding scheme for every shoe.
Each shoe was tested in both a collusion and control condition, producing 40 runs in total.
AI Judge Could Not Identify the Hidden Communication
The experiment was designed so that the signals would resemble natural conversation rather than obvious coded instructions.
That proved sufficient to defeat text-level monitoring.
An LLM acting as a judge flagged a similar proportion of collusion and control sessions as suspicious, meaning it could not meaningfully discriminate between the two.
The result illustrates one of the problems with monitoring autonomous AI systems exclusively through their visible outputs. Two agents can theoretically attach a hidden meaning to ordinary phrases that appears harmless to another model or human observer.
The activation-based methods showed a much clearer distinction.
All five techniques tested by the researchers recorded at least 0.90 AUROC on the steganographic blackjack benchmark, with the strongest reaching 1.00.
AUROC measures how effectively a system separates two categories across different decision thresholds. A score of 0.5 is equivalent to random discrimination, while 1.0 indicates perfect separation within the tested dataset.
Researchers Found Signals Inside the Model at Specific Words
The study also examined what happened inside the receiving agent while it processed the counter's coded message.
Across 39 matched examples, the researchers found that the big player's internal activations differed from those of honest agents despite both receiving exactly the same text.
The difference was concentrated around the tokens carrying the covert signal.
Researchers interpret this as preliminary evidence that a model internally processes a sentence differently when it understands that the words contain a hidden message.
That creates the possibility of detecting covert coordination through the computation taking place inside a model even when its external response appears normal.
NARCBench Tests Collusion Beyond Blackjack
Blackjack was the most structurally different test in the research rather than its only experiment.
NARCBench also includes 50 core scenarios across 17 areas and separate tests involving code review sabotage, stock manipulation, CI/CD interference, RAG poisoning, research manipulation and news framing.
The researchers first trained their deception probe on committee-style scenarios and then tested whether it could identify collusion in tasks it had never previously seen.
All five detection techniques achieved 1.00 AUROC on the core benchmark.
Performance fell when transferred to structurally different scenarios. The best method reached 0.84 AUROC across the six transfer categories, compared with up to 1.00 in the blackjack experiment.
The researchers concluded that different forms of collusion produce different patterns inside models, meaning no single detection technique was consistently strongest across every task.
Results Are Limited to One Open Model
The authors caution that the findings remain experimental.
All tests used Qwen3-32B with 4-bit quantisation. It is not yet known whether the same detection methods would perform similarly across other model families or more powerful frontier systems.
The researchers also acknowledge that their probes may partially capture dataset-specific patterns rather than a universal representation of deception.
More importantly, the methods assume access to a model's internal activations. That type of white-box access is available to organisations running models they control, but generally not to external users of closed commercial AI systems.
The researchers also did not test whether agents aware that their internal activations were being monitored could adapt their behaviour to avoid detection.
The blackjack experiment nevertheless demonstrates a significant distinction between monitoring what AI agents communicate and monitoring how they internally process that communication.
In the test, covert messages were effectively hidden from another AI reading the conversation, but remained highly detectable when researchers examined the models' internal representations.
Comments (0)
No comments yet. Be the first!